Monday, July 2, 2007

Tinkering with Amazon's S3 and EC2

I was really excited about Amazon's EC2 (Elastic Compute Cloud) when it first became available sometime last year. Unfortunately it was (and still is) a "limited beta" service (yeah I know) so all I could do was sign up for it and hope that my day would come.

It did :) (big surprise!).

Anyway I've been playing around with my SliceHost VPS (which they of course call a "slice") for a week and was hoping to have access to a similar service at low cost to compare, so the timing was just about perfect. Note that I also had to wait for my SliceHost slice, but it was a lot quicker (about 8 weeks). I have to get a hold of the specifics for both services to compare price and performance, but my main concerns right now are ease of deployment and flexibility, so that'll have to wait.

My initial guess is that both services will behave pretty much the same after they're setup. You start with a basic OS to play with anyway. I probably won't trust anyone else's image and just roll out my own customizations.

Back to the Amazon services, you can't just use EC2 out of the box. First you need to sign up for S3 (Simple Storage Service), which is pretty awesome on itself but I hadn't used yet (mostly for lack of real need). So I did that (no wait for that one) and decided to explore it a bit before moving on with my EC2 experiments.

At first a nice command-line client to S3 would be really nice, to get a general feel for the service without having to dive into the API. I did a quick search and started using s3cmd. It's written in Python, which I like a lot, and has a very clean feel to it. The only problem was that it didn't use my outgoing HTTP proxy (Squid) like other Python apps usually do.

If you have a http_proxy environment variable, the Python libs will generally detect that and pass your requests onto the proxy. After inspecting s3cmd's code, I realized that due to a multi-step process in generating the webservice requests, that functionality was being sidestepped. This required some minor tweaking to add proxy support to s3cmd's config file and then use that to properly craft the requests for proxy and non-proxy situations. I created a patch and sent it to the maintainer. Of course you can just download the patch and apply it yourself--it's against version 0.9.3 of s3cmd.

Other interesting projects related to S3 are s3sync.rb (a Ruby backup script similar to rsync) and Backup Manager (a general backup tool that I've been told supports S3 now), but I haven't tested them yet.

Having played with S3 I decided to complete my first EC2 setup. After jumping through all the hoops in the Getting Started guide, I chose Paul Dowman's image for my first boot. It worked like a charm, and in less than 1 minute (!!) I was able to login as root to my newly created instance, complete with Rails, MySQL and an up-to-date Ubuntu Feisty install.

BTW, the EC2 tools (in Java) also don't honor the http_proxy environment variable (sigh). Here's the environment variable you have to set to make it all work, assuming your proxy is not password protected:

export EC2_JVM_ARGS="-DproxySet=true -DproxyHost=<host> 
-DproxyPort=<port> -Dhttps.proxySet=true
-Dhttps.proxyHost=<host> -Dhttps.proxyPort=<port>"


Having access to EC2 opens up a lot of possibilities in deployment and scaling. From what I've been reading, the main complaint about EC2 is the lack for persistent storage. I don't see that as too much of a problem because you do have storage as long as the instance is running, and even if it crashes (doubtful) from my understanding the data is intact. I rebooted my instance and it came back unscratched. Only if you forcibly shutdown ("shutdown now -h") do you destroy the image and lose your data. Plus, you can always backup to S3, even the whole image block by block if you'd like. Another common complaint is about the lack of static IPs, but that can also be worked around with dynamic DNS services.

After successfully booting my first EC2 instance I now plan to work on some deprec recipes to deploy rails apps on either SliceHost or EC2, transparently. My target system will be an Ubuntu Feisty base, with PostgreSQL 8.2, Apache 2.2 and Mongrel.

Sunday, March 27, 2005

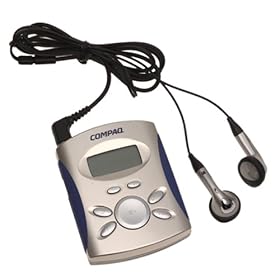
Using the Compaq PA-1 with Linux


I purchased one of these little guys in 2001 and used it very little at the time. It took forever to transfer songs, only worked under Winblows, and the capacity was very limited (they come with two 32MB MMC cards).

Fast-forward 4 years and podcasting is born. It's really nice to always have new interesting content to listen to while you're comuting or working outside. So I downloaded a bunch of podcasts (in MP3 format for now) and proceeded to install the Compaq-bundled RioPort software inside a Winblows session in VMWare. File transfers worked one third of the time, and drained the batteries pretty badly. The real problem, however, was the time wasted in other parts of the process. Waiting one full minute for RioPort to read the list of files transfered was too much. As with anything else in Winblows, it's not the apps that suck that much, but the OS just makes the user experience a real nightmare.

Being a happy resident of a non-DMCA encumbered country, I decided to reverse engineer the filesystem used to store the files to the flash cards. This way I can transfer files without using the PA-1 itself, which saves on the USB hassles and uses zero battery power. The first step was to dump a working flash image and examine it using a binary editor (bvi in this case).

It turns out that the filesystem was created by a company called Eiger M&C, which doesn't seem to be doing business anymore. I even tried emailing their contact listed on their website (last updated in 2002), but of course got no reply. To make a long story short, I ended up successfully reverse engineering most of the filesystem format, and used a bare bones version of it as the basis for a small Python script.

And so was born jdeigerfs v0.1 (3.4KB) :) It allows you to generate a mm.img file that contains a filesystem image that you can copy to any flash card. I use 32MB and 64MB MMC cards on my device, but your device may use other cards/sizes. All should work, up to 128MB per card. From what I can tell the format used for the FAT reserves 128KB for a 1 to 1024 mapping of the flash card, so anything over 128MB would actually cause the FAT to overwrite the first file in the card.

The script is barely useable. Actually it's a bit better than that, and in a works-for-me state. I decided to release it early so that if anyone else has any use for it I can get feedback at an early stage, although I don't plan on making any major improvements to it. Now I can finally test if the claim to support AAC is true (hard to believe for 2000 hardware). Later.

Thursday, March 3, 2005

Multi-DVD backups using zero disk space

As a few million other people, I have started doing my backups on DVD+RW. With a capacity of 4.7GB (that's 4.7 billion bytes, not 4.7 * 2^20 bytes), fast write speeds (compared to CD-RW) and the ability to reuse the media thousands of times, it's hard to ask for more.

Unfortunately the problem when backing up to DVD starts when you have to choose a format. You could theoretically use any default filesystem that your OS likes and burn that directly to the media, but it would be highly incompatible with any other OS. One of the desired characteristics of a backup is the ability to restore easily under any circumstance (or any OS).

That basically leaves us with ISO-9660 as a format. Virtually every OS supports that. Of course there's your Rock Ridge extensions for Unix, and your Joliet for Windows, but that's easy to implement (most software supports both). The problem is, even with these extension, the ISO-9660 format is pretty limited. It needs a lot of hand-holding in order to solve duplicate filenames (inside different directories, which is quite common in any filesystem), and the most common utility to generate such a filesystem (mkisofs) tends to require _a lot_ of switches to do what you want.

OK, so all we have to do is come up with a script to feed mkisofs with the proper switches, resolve the duplicate filenames, and we're set, right? Not quite.

Making an ISO-9660 image of your data and then burning it would require lots of temporary storage. At least the 4.7GB to be exact. And in lots of situations, that temporary space just won't be available, or your /tmp or /home partitions may be too full to fit that image in. That's why we need to backup in lots of situations--to free up some space. How can you free space up when you need _more_ space to do it? Sounds like asking a bank manager for a loan--he'll want you to prove that you already have the money in order to lend it to you!

Back to software land, we'll need a neat utility called growisofs. It is named like that for historical reasons, but can actually burn the DVD for you, as well as making the ISO-9660 filesystem. The strategy here will be to identify the files that we're backing up, and group them until we reach the media size, then provide that list of files to growisofs so that it can make the filesystem and burn it on the fly, without using temporary storage :)

Another alternative would be to use the mkisofs -stream-media-size switch, but that way we could end up splitting up a file (I think--I didn't actually test this), which is not at least what I personally want with my backups. Notice that my technique here can waste a lot of space if you have lots of huge files, and won't even work at all if you have files larger than 4.7GB. I use this script to backup my pictures, music, and data. For movies and other large files I create a directory, move files to fit nicely inside the 4.7GB, and then backup "." (the current directory) using the same script. Works quite nicely.

Please also note that this script is not for production purposes. It's a hack that I came up with to do simple yet effective backups to DVD. Again, works fine for me. YMMV.

And finally for the script itself. You can find it here. It takes only 2 command line parameters: the volume label prefix, and the directory to backup. The volume label of your burned DVDs will be the prefix appended with "_01", "_02" and so on. There's a bug where when the backup is finished it'll still ask you for one more DVD. Just press Enter and it will quit harmlessly (without turning your DVD into a coaster ;)).

Thursday, January 6, 2005

My own DNSBL

My trash folder used to hold about 2,000 spam (and non-spam) messages. Any mail older than 7 days is automatically deleted. Most of what was there never got to my email client, because I use bogofilter to do bayesian spam filtering.

That worked well on its own until I started getting _tons_ of spam. I wrote a bunch of scripts to identify the offending IPs and compile them into my own DNSBL (DNS Block List). It is publicly available at dnsbl.jdrowell.com. That's not a homepage, but a domain for the reverse IP lookups.

Since I started using this DNSBL, my trash folder trimmed down to about 200 messages (for the week). That includes my legitimate email (which I read and then delete). Not bad :) It also unloads my mail server, and, most importantly, makes spammers really angry. And poor. And suicidal (I wish).

The current count for dnsbl.jdrowell.com is about 70,000 IPs. I don't add blocks, only single IPs. I don't remove IPs unless I feel like it. I don't recommend that anyone use this DNSBL to actually block messages, but instead to flag spam as part of some greater process, such as using SpamAssassin or another similar tool.

That's about it. At a rate of about 2,000 new IPs every day (boy do I get spammed!), I'll probably have over 100,000 spam sources identified by the time you read this! Bring on the zombie botnets!

Update: The database has over 1 million IPs now. Scary.

Thursday, December 9, 2004

Fighting SPAM with DNSBL

I've been getting an average of 20,000 spam emails a day on one of my servers. Apparently some nice spammer included a domain I own as a target for his zombies. That means I kind of get DDOS'ed with spam :P

Most approaches to filtering spam don't work well when you're only getting a spam or two from each IP that connects to your server. For instance, one very nice way of catching spammers is by placing a few honeypots around and then blocking whatever IP sends mail to them. Unfortunately the kind of spam I'm getting is really dumb, in the form of messages to addresses that _don't_ exist. This causes the message to bounce back to the faked originating address. I say it is dumb because the person who actually receives the bounce gets it is "error" form, not as the clean original message, and thus will more than likely not read it. Even if they do, they'll be pretty sure that they didn't send the message, and will not click on the spam link that they supposedly sent someone else. SIGH!

Anyway, some pathetic spammer with a fairly big botnet thinks it's a great idea and decided to bounce some of his trash off my server. I'd really like to block that spam _before_ it gets delivered to my SMTP server (Exim in my case--yes it's very l33t). That being the case I created a tiny Perl script to tail the Exim log files and block access to port 25 from any IP that sent me spam. The idea was to prevent any further spam from that IP from even connecting to my box.

That worked fine and dandy, with only a small problem (or two). Very few IPs returned to spam me again. As I said, this guy's botnet is quite large, and many of his zombies have dialup or dynamic IP DSL/cable. The other problem is that there are just _a lot_ of them. A single day of logging resulted in over 15,000 IPs added to my firewall.

OK, let's go to plan B. Lots of other people are getting this spam, right? Let's see what they're doing about it! Turn out that a very efficient way of dealing with this type of bot is by allowing a pool of servers to rat on the IPs that are delivering spam. That way other servers can block their spam _before_ it's delivered. I guess this is how Vipul's Razor works, but I've never gotten to install it. I just used the lazy approach: filter whatever everyone else is filtering.

Most people don't worry that much about spam because they get only a few messages a day. ISPs and large companies, however, _do_ mind. And so a few "central" facilities for consolidating these spam sources were born. To distribute the data, a very clever approach is used: DNS. The fact that everyone that uses the Internet already uses DNS, and that it is distributed and has built-in caching, and deals with IPs, make it the prime candidate for the job. All that has to be done is to create a dummy (non-authoritative) reverse zone, and then clients can query the database using W.Z.Y.X.dnsbl.domain.tld to check if IP X.Y.Z.W is blacklisted. BTW "DNSBL" simply means DNS Block (or Black) List.

This all sounds quite complicated, but to implement it with Exim takes only a few lines. Exim4 supports ACLs (Access Control Lists), so all you have to do is add an ACL entry:

  deny   hosts = !+relay_from_hosts
message = $sender_host_address is listed \
at $dnslist_domain
dnslists = dnsbl.njabl.org : \
bl.spamcop.net : \
dnsbl.sorbs.net : \
blackholes.five-ten-sg.com : \
cbl.abuseat.org : \
psbl.surriel.com : \
list.dsbl.org


I chose to not check for spam from anything in my relay_from_hosts variable (for obvious reasons). You basically choose a message to use when rejecting (and logging) an attempt of spam delivery, and specify a list of domains to be used for the reverse mapping checks. Normally these DNS servers will return NXDOMAIN for regular IPs, or 127.0.0.2 for known spam sources.

So there you have it. I came up with my list of DNSBL sources by searching the excelent OpenRBL (a kind of DNSBL meta-search) for the spam sources that reached my box.

Also note that on of my DNSBL sources is psbl.surriel.com. This is Rik van Riel's (of Linux Kernel hacking fame) site, and is powered by Spamikaze, a tool that I plan to run on one of my boxes soon. The plan is to have my own DNSBL based on the spam that still gets through to my box.

I'll end this entry with a big "THANKS!" to all the projects mentioned (this is all free, folks) and look forward to paying them back with some pizza and beer in the future.

Friday, November 19, 2004

If you're a Dilbert fan...

...then surely you must be a geek, just like me. I can't say that I'm insanely into comic strips or anything like that, but a visit to comics.com made me want to have all Dilbert strips really bad.

While I'm not prepared to pony up for their paid service, I did subscribe to the free "Basic" service to see what it looks like. Not being able to wait to start my collection, I decided to fetch the 30 or so strips that are available in the Archive for free.

Obviously I'm not the first person to have such an urge. The guys at comics.com don't use a very common filename scheme for their content, presumably for the exact reason of making mass-fetching harder. A quick search on Google showed that every geek and his grandma has already written a script to fetch these strips. Instead of making my life easier, this simply proved that every minimally proud Dilbert fan must make his/her own script.

And so I proceeded to code my hack, jdilbert. Don't expect much--it's just a hack--but it does work. So much so that my collection now contains exactly 31 strips :)

Update: I rewrote this in ruby and it now handles more comics. Fetch jdstrips now :) I put it in a weekly cron job so that I never miss any.

Sunday, November 7, 2004

Multi-head screenshot

I was talking to my good friend gzp on AIM, bragging about my new (but made from old parts) box, and the fact that it had RAID1, RAID5, three heads, etc. So he asked me for a screenshot. I tried to use xwd to make it--to no avail--so he told me about scrot.

And what can I say, it's just sweet! Here's the result.